Essai 01 · Project Causal Lab
Counterfactual programme steering
Toy scenario
Counterfactuals · An open enquiry
The archive digitisation backlog · Fictional decision brief
You manage an archive digitisation team. Scanning is outpacing catalogue checking, unfinished batches are accumulating, and the collections director needs a pilot recommendation by Friday. Choose one first intervention: increase automation by 0.15, add two qualified cataloguers, or reduce the number of batches allowed in progress by two. The aim is to complete more usable batches without concealing longer waits or more cataloguing defects.
| Control or outcome | Archive interpretation |
|---|---|
| Staffing S | Qualified catalogue-checking capacity in FTE. The +2 preset assumes two additional qualified people are available; recruitment and learning time are outside the model. |
| Automation A | A consistently defined automation fraction from 0 to 1. The +0.15 preset means 15 percentage points, not 15% more than the baseline. |
| WIP limit W | The maximum number of standardised batches allowed in progress. The −2 preset reduces that cap by two; it does not automatically complete or discard existing work. |
| Throughput T · Lead time L · Defects D | Completed batches per week, days per batch, and defects per batch. Define comparable batch sizes, difficulty and acceptance checks before collecting real measurements. |
| Unplanned work U · Rework R | Indices whose meaning and measurement must be fixed before any archive telemetry is fitted. They are not staff hours or counts of rejected batches by definition. |
Evidence to seek. Check pre-rollout rosters and specialist skills, the rule allocating automation, batch difficulty, and whether similar teams had a real chance of receiving either level of automation. Capacity measured after rollout can already reflect the intervention. The three-node graph omits other possible causes; its adjustment result is conditional on its declared arrows.
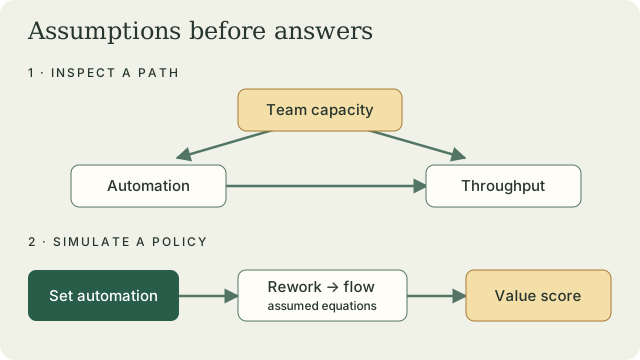
What this run establishes. The two lessons let you inspect an assumed causal account and rehearse a policy comparison. The 52-week sample was generated for the original delivery model; it is not an archive record. The graph and simulator remain separate. A real pilot decision also needs costs, onboarding time, a measurement plan and agreed quality thresholds; the simulator does not forecast a backlog clearance date.
An archive has a growing digitisation backlog. Would more automation help, or do teams with more specialist capacity both automate and finish more? Examine that claim, then compare three possible pilot policies in a separate, assumed delivery model.
Essai 01 · Project Causal Lab
Toy scenario
These modes share a question, not a fitted model. Drawing an arrow does not establish a cause, and fitting a regression does not identify an intervention.
Start with the displayed team-capacity example. Condition on Team Capacity to block the back-door path, then clear that condition. Or challenge the Capacity → Automation arrow below and see how the required adjustment changes. The original six-variable project map remains in Teaching example.
Specialist capacity may affect both automation adoption and throughput. Alternatively, an external rollout schedule could set adoption independently of capacity. These are two assumed stories; the buttons compare their consequences.
Each choice replaces the current editor graph with the three-variable example and clears conditioning. It changes an assumed causal story, not the team’s policy or the separate simulator.
With the arrow, Automation ← Capacity → Throughput is an open back-door path; conditioning on measured Capacity blocks it. Without that arrow, this particular path disappears and the empty set passes in this three-variable graph.
1 · Source. Tatlidil and colleagues (2025), A comparison of methods to elicit causal structure, compare drawing graphs with asking pairwise questions about imagined interventions on everyday objects. We borrow the question-first method. It elicits causal judgements, not effect sizes; applying it to project work is our teaching adaptation.
2 · Judgement. In this team, capacity means specialist time available before automation rollout. If that time changed, would automation adoption change? One proposed mechanism is that spare specialists can build and introduce automation. A competing story is that an external rollout schedule sets adoption independently of team capacity. These are hypotheses to investigate, not findings from the paper.
3 · Calculation. Compare those stories below. Both retain Capacity → Throughput and Automation → Throughput. Changing the one disputed arrow changes what the back-door test requires before estimating automation’s total effect.
Define the intervention and its timing, ask people who know the rollout mechanism, and examine allocation rules and evidence that could contradict the story. A “yes” can describe an indirect route: check for mediators before asserting a direct arrow. The paper’s procedure removes some direct links when an indirect route exists, an assumption tailored to its objects. We do not apply that rule here: both routes can exist in projects.
The earlier June 2026 CausalNex/DoWhy project-control spike captured an assumed graph and calculated an intervention estimate. Its synthetic generator encoded the assumed signs, so the result illustrated the workflow rather than validating the arrows. This example puts the elicitation step before calculation.
Evidence boundary. Deleting an arrow assumes the influence is absent; it does not demonstrate absence. The identification claim also needs the rest of the graph, including missing causes, to be defensible, plus consistent interventions and adequate overlap in the data. Neither this elicitation exercise nor a passing graph test supplies an effect estimate or proves a policy will work. Pearl (2009), §3.3.1, supplies the adjustment criterion.
Green dashed arrow: directed route · Rust arrow: displayed back-door route · Gold box: collider on a displayed path · double border: conditioned · dashed box: unobserved
“Open” means d-connected on this path under the selected conditioning set. A back-door path begins with an arrow into X; some are already blocked. An open path does not prove a nonzero effect.
A directed acyclic graph (DAG) represents a proposed causal story. An arrow asserts a direct influence relative to the variables included. The original map keeps Scope Creep, Interface Misalignment, Vendor Capacity, Design Risk, Delay and Cost Overrun. Edit it to expose disagreements before analysing it.
A chain X → M → Y carries a directed causal route. A fork X ← C → Y can create association through a common cause. In X → C ← Y, C is a collider on that path. Conditioning on C, or a descendant of C, opens that route unless another non-collider blocks it. A variable can be a collider on one path and a non-collider on another.
A directed path is not the “front-door criterion”. This tool does not implement front-door identification.
For Pearl’s back-door criterion, the set contains no descendants of X and blocks all paths beginning with an arrow into X. This lesson tests that criterion exactly and lists all inclusion-minimal observed sets: removing any member would invalidate the set. “Minimal” need not mean the fewest variables.
The calculation removes outgoing arrows from X and checks d-separation. It assumes the graph is correct, including its missing arrows, and uses explicit unobserved nodes rather than bidirected edges. It does not test data quality, overlap/positivity, consistency or the truth of those assumptions. If no observed set passes this sufficient criterion, the effect may still be identifiable by another method.
The loaded sample contains 52 synthetic weeks of staffing, automation, WIP limits and outcomes from the original delivery example. Use the archive interpretation on the Scenario page to frame a possible trial. Fit the stated equations, then compare a fixed baseline with changed controls. This is an intervention simulation under assumptions, not a recovered counterfactual for a real week.
Unplanned work U is external to the policy. R depends on U,A,W,S; T on S,A,U,R,W; L on W/T; D on U,R,A,T. The value score is a chosen trade-off, not money or a validated programme objective.
Green = selected policy; gold outline = baseline. Histograms show simulation counts; the score plot shows 5th–95th percentiles and an interquartile box. These spreads omit coefficient and model uncertainty; they are not confidence intervals.
Each option uses the same random draws. A zero change therefore has exactly zero simulated difference. All controls are fixed at baseline means plus the requested changes; “baseline” is itself a model scenario, not the observed history.
Choose a policy and inspect its simulated throughput, lead time and defects. Compare the presets, then try a custom change. These results can help frame questions for a small, measured trial. They cannot select a proven best policy for a real programme.
Imported telemetry changes the fitted coefficients. It does not validate the causal story or make the proposed action equivalent to a randomised experiment.
The model fixes staffing S (FTE), automation A (0–1) and WIP cap W (items). It draws an unplanned-work index U, then rework index R, throughput T (items/week), lead time L (days) and defects D (defects/item). It scores each draw using the original weights 2, −0.03 and −1.5.
Costs of extra staffing or automation are absent. Rank changes are conditional on those chosen weights and the model. Examine the outcome columns, observed input ranges, clipping counts and sensitivity to assumptions before proposing a trial. Smaller spread alone does not establish a safer intervention.
R := c0 + c1·U + c2·A + c3·W + c4·S + εR
T := a0 + a1·S + a2·A + a3·U + a4·R + a5·W + εT
L := b0 + b1·W/T + εL
D := d0 + d1·U + d2·R + d3·A + d4·T + εD
Separate least-squares regressions fit the four equations. Simulation assumes invariant equations and independent Gaussian errors with fitted residual standard deviations. U uses the sample mean and sample standard deviation, with negative draws set to zero. Policies share the same shocks for a reproducible comparison. Error independence, linearity, stable units and the absence of omitted confounding are assumptions, not regression findings. Time dependence and changing regimes are omitted.
Controls are bounded at S ≥ 0, A ∈ [0,1], W ≥ 1. Simulated values are floored at R,D ≥ 0, T ≥ 0.05 items/week and L ≥ 0.1 days. These are declared numerical modelling choices; extensive clipping is a warning about model mismatch. Least squares fits the unclipped equations, so clipping changes their simulated means. Zero-noise propagation is not the mean of a nonlinear simulation.
The lead-time equation is an empirical WIP-cap proxy. Little’s law concerns average occupancy = flow rate × average time under appropriate stable-system conditions. A WIP limit is not measured occupancy, and W/T in weeks requires a time conversion to days. The fitted intercept and slope absorb a local empirical relation; no queueing identity is enforced here.
A unit counterfactual needs evidence-conditioned abduction of the unit’s disturbances, an action, then prediction with those disturbances. This app samples new scenarios and performs no such abduction. Coefficient uncertainty, causal identification, formal influence-diagram optimisation, EVPI/VOPI, budget constraints and SLA optimisation remain outside this trial.
These browser checks are smoke checks. The repository also tests graph criteria against an independent path oracle and regressions against known solutions.
End. Understand what would change under a different management policy, and which parts of that answer come from evidence or from assumptions we supplied. This is an early trial, open to revision.
Ways. Pearl’s causal graphs distinguish association from intervention; the back-door criterion tests a sufficient adjustment condition within an assumed graph. Structural equations then give a separate, explicit way to propagate policy changes. The sources and their limits are explained below.
Means and result. The two interactive modes retain the original project map, 52-week synthetic sample and policy choices while repairing their calculations and explanations. The graph editor does not generate the policy simulator. The simulator compares newly sampled scenarios; it does not reconstruct what would have happened in one observed week.
Still open. Whether a defensible causal model and obtainable project evidence can support an actual management intervention remains unresolved. Correct arithmetic and a plausible diagram do not settle it.